The best AI model in November 2026 is Claude Opus 5.5 for coding and agents, GPT-6.1 Terra for writing, Gemini 4 Carbon for multimodal work and long documents, and DeepSeek V4.1 Flash for budget volume work on open weights. Input prices run from $0.10 per million tokens (GPT-6 Luna, Claude Haiku 5.5) to $10 (GPT-6 Astra), read in USD on each maker’s official pricing page on November 15, 2026, before Google’s December 1 price rise on Gemini 4.
Quick verdict
For developers buying API usage and anyone choosing which plan’s model to pay for; app shoppers should start with my list of the best AI chatbots compared as apps.
Per million tokens, Opus 5.5 lists $4 input and $20 output, against $0.15 and $0.60 for DeepSeek V4.1 Flash off-peak.
The trade-off: BenchLM, LMArena and Artificial Analysis rank Claude Fable 5.2 first, at twice Opus 5.5’s price. Kimi K3.1 Pro is the open-weight alternative.
Claude Opus 5.5
Best for: coding and long-running agents
Anthropic’s own starting recommendation, at $4 input and $20 output per million tokens.
Limit: BenchLM, as of November 13, 2026, ranks Fable 5.2 above it
GPT-6.1 Terra
Best for: writing and computer use
OpenAI describes it for clear, natural writing and precise computer use, at $1 input and $5 output per million tokens.
Limit: not in ChatGPT’s plan table, so it is an API pick
Gemini 4 Carbon
Best for: images, audio, video and long documents
Google lists text, image, audio, video and PDF input for it, with a 1M-token context.
Limit: the API price doubles on December 1, 2026
DeepSeek V4.1 Flash
Best for: budget volume work on open weights
Off-peak calls cost $0.15 input and $0.60 output per million tokens, with a 384K maximum output.
Limit: weekday peak hours double every rate
In This Article (16 sections)
Quick Comparison: Best AI Model for Each Task
Match the model to the job: Opus 5.5 for coding agents, Fable 5.2 for hard reasoning, Terra for writing, Gemini 4 Carbon for mixed media, Kimi K3.1 Pro for open weights and Grok 4.7 for live search.
| Task | Pick | Runner-up | Published result |
|---|---|---|---|
| Coding and agents | Claude Opus 5.5 | Claude Fable 5.2 | LMArena agent board: Fable first, Opus second |
| Hard reasoning | Claude Fable 5.2 | GPT-6 Astra | BenchLM: Fable first (Estimated). LLM Stats: Astra leads GPQA |
| Writing and computer use | GPT-6.1 Terra | GPT-6.1 Sol | OpenAI’s description: clear, natural writing. BenchLM: best balance of cost and performance |
| Images, audio, video, long PDFs | Gemini 4 Carbon | Gemini 4 Hydrogen | BenchLM: second place |
| Lowest input price among the picks | GPT-6 Luna | Claude Haiku 5.5 | Same input price as Haiku, whose rate rises fivefold past 100,000 tokens |
| Budget volume on open weights | DeepSeek V4.1 Flash | GLM-5.3 | Artificial Analysis: second among open-weights models |
| Open weights | Kimi K3.1 Pro | Qwen3.8 | LLM Stats: best open-weights model |
| Live web and X data | Grok 4.7 | GPT-6.1 Terra, with its web search tool | None cited |
BenchLM scores Claude Fable 5.2 at 93.7, a figure it labels Estimated, ahead of Gemini 4 Carbon (89.2) and Claude Opus 5.5 (86.6). LMArena‘s agent board orders the same three Fable, Opus, Carbon. Artificial Analysis lists Fable as its highest-intelligence model. On LLM Stats, GPT-6 Astra leads the GPQA reasoning benchmark at 96.0% and Kimi K3.1 Pro leads the open-weights models at 94.2%.
My take
I would pick by job, not by leaderboard position: BenchLM and LMArena’s agent board name the same top three, in different orders. BenchLM itself calls its first rows “a shortlist, not a purchase order”.
The ten picks side by side:
| Model | Best for | API price per 1M tokens (input / output) | Context window (tokens) | Plan that includes it | Key limitation |
|---|---|---|---|---|---|
| Claude Opus 5.5 | Coding and long-running agents | $4 / $20 | 1M | Claude Pro, $17 a month billed annually | Fable 5.2 ranks higher on BenchLM |
| GPT-6.1 Terra | Writing and computer use | $1 / $5 | 1.05M | Not in ChatGPT’s plan table | Ninth on BenchLM |
| Gemini 4 Carbon | Images, audio, video and long documents | $2 / $10 through Nov 30, 2026; $4 / $20 after | 1M | Google AI Ultra, from $99.99 a month | Not on the free API tier |
| DeepSeek V4.1 Flash | Budget volume work on open weights | $0.15 / $0.60 off-peak; $0.30 / $1.20 peak | 1M | Not listed on the pricing page | Peak hours double the rate |
| Kimi K3.1 Pro | Open-weight model by third-party rankings | $2 / $10 | 1,048,576 | No subscription; pay as you go | Priced like a closed flagship |
| Grok 4.7 | Real-time X and web search | $2 / $6 | 500,000 | Not listed on the models page | No current events without search tools |
| Qwen3.8 | Running a model on your own hardware | $2 / $6 (Qwen3.8-Max) | 1M input per request | Not listed on the pricing page | Free quota only in Singapore |
| Mistral Large 4 | A European vendor with open weights | $0.5 / $1.5 (as Mistral Large) | Not listed on the models overview | Plans do not name the model | 84th on BenchLM |
| GLM-5.3 | Budget agentic coding | $1.4 / $4.4 | 1M | GLM Coding Plan, from $18 a month | Text-only input |
| Muse Spark Open | US-made open-weight model | Not listed on Meta’s developer page | Not listed | Not listed | 103rd on BenchLM (Estimated) |
Sources: Claude models, Claude plans, OpenAI models, ChatGPT pricing, Gemini API pricing, Google AI plans, DeepSeek, Kimi, Grok, Model Studio, Mistral, Z.ai, GLM Coding Plan and Meta, checked November 2026.
How I Chose These Tools
I considered the picks below and the models under Also Considered. Each needed an official page that states its name and limits; I then ranked by job fit on named public leaderboards, price per task, context window, input types, open weights and plan access.
Prices and limits come from the makers’ pricing and documentation pages, read on November 15, 2026. This ranking does not measure output quality on your prompts, so replay some of your own prompts on your top models before you commit.
API Prices, Context Windows and Cost per Task (November 2026)
Take one illustrative workload: 1,000 tasks that each send 20,000 input tokens and return 2,000 output tokens, or 20 million input and 2 million output tokens in total. It costs from $3 on GPT-6 Luna or Claude Haiku 5.5 to $300 on GPT-6 Astra. Each row adds the input cost (20 x the input price) and the output cost (2 x the output price); for Opus 5.5 that is 20 x $4 + 2 x $20 = $120.
| Model | Price per 1M tokens (input / output) | Cost of 1,000 tasks (20 x input price + 2 x output price) | BenchLM rank |
|---|---|---|---|
| GPT-6 Astra | $10 / $50 | $200 + $100 = $300 | 4 |
| Claude Fable 5.2 | $8 / $40 | $160 + $80 = $240 | 1 (Estimated) |
| Claude Opus 5.5 | $4 / $20 | $80 + $40 = $120 | 3 |
| Gemini 4 Carbon, from Dec 1, 2026 | $4 / $20 | $80 + $40 = $120 | 2 |
| Gemini 4 Neon | $3 / $15 | $60 + $30 = $90 | Not ranked (Nov 19, 2026) |
| Gemini 4 Carbon, through Nov 30, 2026 | $2 / $10 | $40 + $20 = $60 | 2 |
| GPT-6.1 Sol | $2 / $10 | $40 + $20 = $60 | 5 |
| Kimi K3.1 Pro | $2 / $10 | $40 + $20 = $60 | 18 (Estimated) |
| Grok 4.7 | $2 / $6 | $40 + $12 = $52 | Not listed |
| Qwen3.8-Max | $2 / $6 | $40 + $12 = $52 | 35 |
| Gemini 4 Hydrogen | $1.50 / $7.50 | $30 + $15 = $45 | 11 (Estimated) |
| GLM-5.3 | $1.4 / $4.4 | $28 + $8.80 = $36.80 | 48 |
| GPT-6.1 Terra | $1 / $5 | $20 + $10 = $30 | 9 (Estimated) |
| Mistral Large | $0.5 / $1.5 | $10 + $3 = $13 | 84 (Mistral Large 4) |
| DeepSeek V4.1 Flash, off-peak | $0.15 / $0.60 | $3 + $1.20 = $4.20 | 31 |
| GLM-5.3-Flash | $0.15 / $0.50 | $3 + $1 = $4 | 59 (Estimated) |
| Qwen3.8-Flash | $0.15 / $0.47 | $3 + $0.94 = $3.94 | Not listed |
| GPT-6 Luna | $0.10 / $0.50 | $2 + $1 = $3 | 47 |
| Claude Haiku 5.5 | $0.10 / $0.50 | $2 + $1 = $3 | 20 |
Sources: illustrative workload at list prices from Claude, OpenAI, Gemini, Gemini 4 Neon, Grok 4.7, DeepSeek, Kimi, Model Studio, Mistral and Z.ai, checked November 2026; ranks are BenchLM’s.
Claude Haiku 5.5 is the outlier: it ties for the lowest total and still sits 20th on BenchLM, above every open-weight model except Kimi K3 and Kimi K3.1 Pro.
Muse Spark Open has no row: Meta’s developer page lists no token price. Three rules move a real bill away from the list price:
- Thinking tokens bill as output. Google labels its output price “including thinking tokens”, so longer reasoning bills more than the answer you read.
- Long prompts change the rate. Grok 4.7 charges different rates above 200K of context, and Claude Haiku 5.5 charges five times its base rate once a prompt passes 100,000 tokens.
- Discounts carry conditions. Anthropic’s Batch API takes 50% off, Kimi’s batch rate is 60% of standard, and DeepSeek’s rate doubles in its weekday peak windows.
1. Claude Opus 5.5: Best for Coding and Long-Running Agents
Start with Opus 5.5 if you build coding agents. Anthropic tells developers to begin there for most workloads and to move to Claude Fable 5.2 only for demanding reasoning and long-horizon agentic work. LMArena’s agent board, read on November 15, 2026, ranks Fable first and Opus second, ahead of Gemini 4 Carbon.
Fable costs exactly twice Opus, and Anthropic’s rule for paying it is narrow: switch when your evals on Opus at higher effort still fall short. All four current Claude models share the 1M context and 128K output, so routine steps can drop to Sonnet 5.5 or Haiku 5.5.
I would default to Opus 5.5 and escalate only the failures to Fable 5.2.
The Batch API takes 50% off for jobs that can wait, and US-only inference adds a 1.1x multiplier.
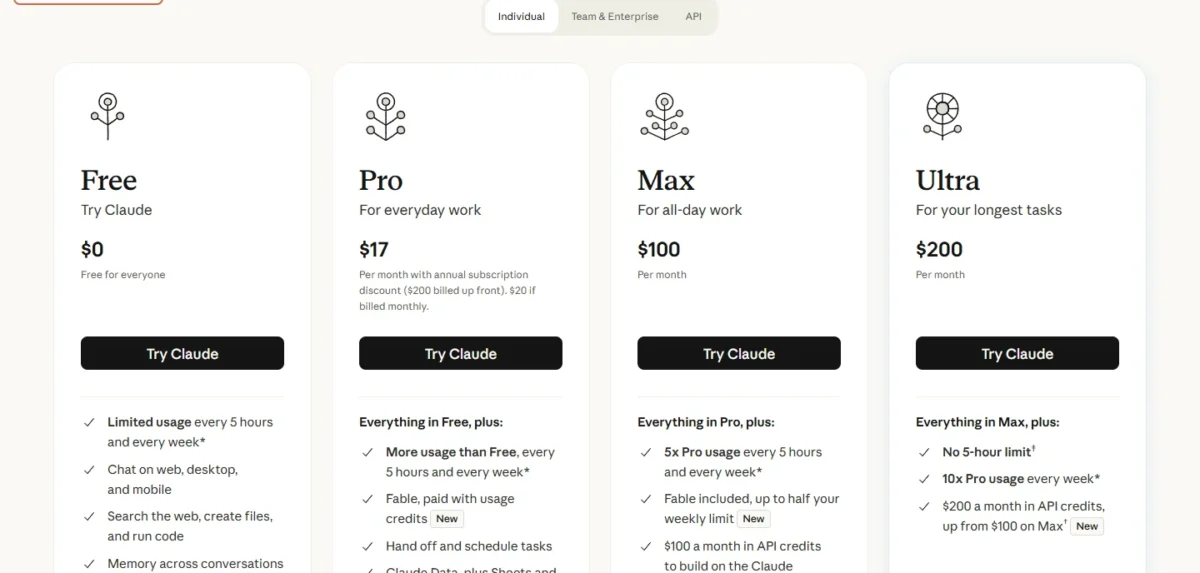
- Claude Pro: $17 a month billed annually, with Opus
- Claude Max: $100 a month, the first plan that includes Fable
Sources: Claude plans, checked November 2026.
Pros
- Anthropic’s own starting recommendation
- First and second on LMArena’s agent board (Fable 5.2, Opus 5.5)
- One 1M-token context from Fable down to Haiku 5.5
Cons
- Twice Gemini 4 Carbon’s token rate until December 1, 2026
- Fable 5.2 doubles the bill again
- Claude Free includes neither Opus nor Fable
- Skip it if:
- your workload is high-volume classification or extraction where a miss costs little. Claude Haiku 5.5 starts at a fortieth of the Opus input price.
For the agent rather than the model, my Codex vs Claude Code comparison covers the coding tools built on these models.
2. GPT-6.1 Terra: Best for Writing and Computer Use
OpenAI sells six GPT-6 models, counting GPT-6.2 Astra and GPT-6.2 Sol from November 17, 2026, with the same 1.05M context and the same four tools (functions, web search, file search and computer use), so the choice inside the family is price against capability. The benchmark boards quoted on this page were read before the GPT-6.2 release, so they do not rank either GPT-6.2 model yet. OpenAI describes Terra as a fast, efficient model for visual reasoning, precise computer use and “clear, natural writing”, and my writing label rests on that description and its $1 / $5 price. Its limit is rank: BenchLM’s table, with data as of November 13, 2026, places it ninth, with a 79.6 score marked Estimated.
GPT-6.2 Astra, OpenAI’s flagship for complex reasoning and coding since November 17, 2026, costs eight times Terra’s rate at $8 / $40, GPT-6 Astra costs ten times it, and GPT-6 Luna takes high-volume work at a tenth of it.
For drafting, editing and browser automation I would start on Terra and move a prompt to Sol or Astra only when its output fails review.
Terra is an API pick: ChatGPT’s plan table lists GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna, but no GPT-6.1 Terra.
- ChatGPT Go: $8 a month, with GPT-6 Luna
- ChatGPT Plus: $20 a month, adds GPT-6 Astra and GPT-6.1 Sol
Sources: ChatGPT pricing, checked November 2026.
Pros
- The flagship’s context and tools at a tenth of its token price
- Described by OpenAI for writing and precise computer use
- BenchLM’s pick for balance of cost and performance
Cons
- Ninth on BenchLM with an Estimated score
- Missing from ChatGPT’s plan table
- The step up to GPT-6 Astra costs ten times as much
- Skip it if:
- the job is multi-step reasoning or agentic coding where a wrong answer is costly. Pay for GPT-6.2 Astra or GPT-6 Astra, or use Claude Opus 5.5.
For the subscriptions rather than the API, my ChatGPT vs Gemini comparison sets the two plan ladders side by side.
3. Gemini 4 Carbon: Best for Images, Audio, Video and Long Documents
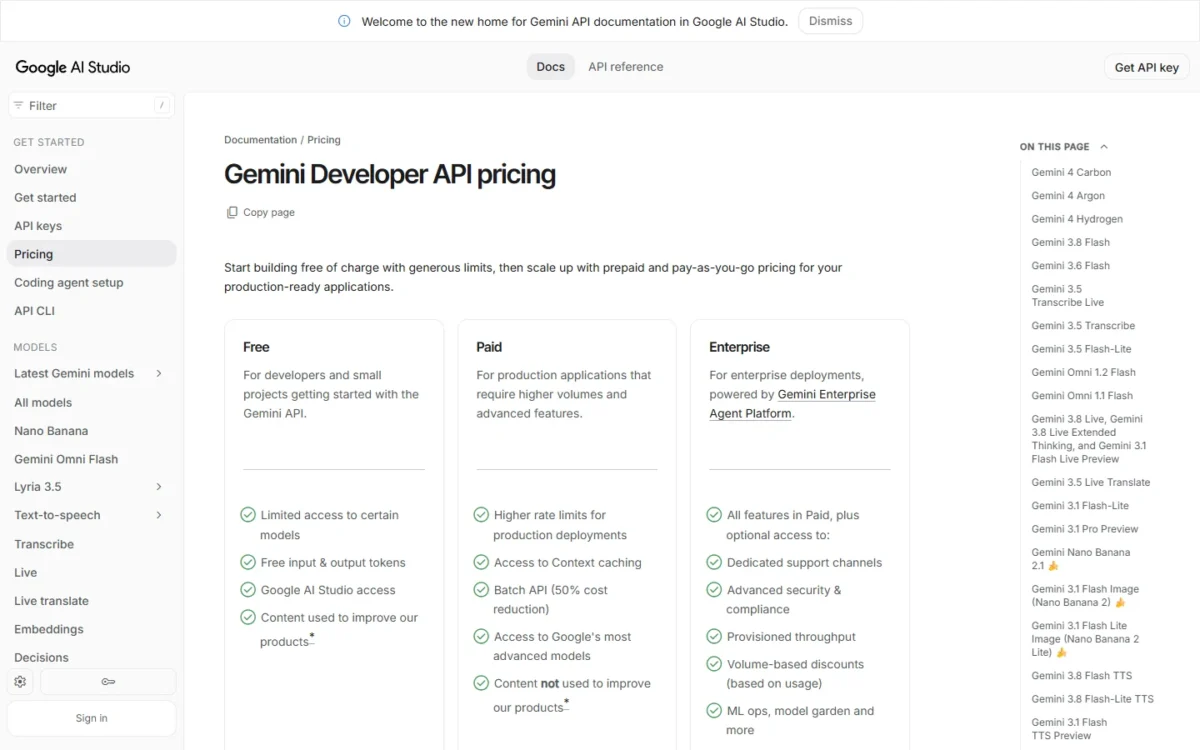
When the input is a recording, a video or a long PDF rather than plain text, Gemini 4 Carbon is the pick. Google lists text, image, audio, video and PDF as its modalities, where Anthropic and OpenAI list text and image input for their current models. BenchLM ranked it second at 89.2 as of November 13, 2026.
Price change on December 1, 2026
Gemini 4 Carbon and Argon cost $2 input and $10 output per million tokens through November 30, 2026, then $4 and $20. The same workload doubles in cost overnight and lands level with Claude Opus 5.5.
Carbon is not on the free API tier, but Gemini 4 Hydrogen is, with the same modalities and 1M context. Prototype there, with one caution: Google’s table marks free-tier usage as used to improve its products, so keep confidential files on the paid tier.
Gemini 4 Neon, which Google began rolling out on November 18, 2026, is the middle model: Google says that while Carbon takes the hardest, long-horizon projects and Hydrogen fast everyday execution, Neon “balances depth and efficiency.” It lists $3 input and $15 output per million tokens with a 1M-token context, above Carbon’s rate through November 30 and 25% below it from December 1. BenchLM had not ranked it as of November 19, 2026, so it is not a pick here.
Carbon is worth it when your pipeline is audio, video or PDF-heavy; budget it at the December price.
Chat access to Carbon costs five times Google AI Pro, the plan that carries Neon.
- Google AI Pro: $19.99 a month, with Gemini 4 Neon and Gemini 4 Hydrogen
- Google AI Ultra: from $99.99 a month, with Gemini 4 Carbon
Sources: Google AI plans, checked November 2026.
Pros
- Text, image, audio, video and PDF input in one flagship model
- 1M-token context and generation up to 1M tokens
- Gemini 4 Hydrogen offers the same input types on a free API tier
Cons
- API price doubles on December 1, 2026
- Output price includes thinking tokens
- In the Gemini app, Carbon needs Google AI Ultra
- Skip it if:
- your input is text only and your budget is fixed past December 1. GPT-6.1 Sol lists the same price today, and Kimi K3.1 Pro adds open weights.
On the subscription side, my Gemini vs Claude comparison shows which plan includes which model.
4. DeepSeek V4.1 Flash: Best for Budget Volume Work on Open Weights
The clock matters more than the model here. DeepSeek V4.1 Flash bills half price outside its weekday peak windows, with a 1M context and a 384K maximum output, and its Hugging Face page lists MIT-licensed weights. It is a volume model: BenchLM had it 31st at 64.5 as of November 13, 2026.
The peak windows, 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays, suit US teams. In Eastern Standard Time they run 8 to 11 p.m. the evening before and 1 to 5 a.m., so a job that runs during the US workday bills off-peak.
Qwen3.8-Flash and GLM-5.3-Flash list lower output rates, but BenchLM ranks DeepSeek V4.1 Flash 31st and GLM-5.3-Flash 59th. I would use it for work I can schedule, and only when open weights or very long outputs matter.
DeepSeek deducts usage from a topped-up balance and says it may adjust prices, so recheck the page before a large run.
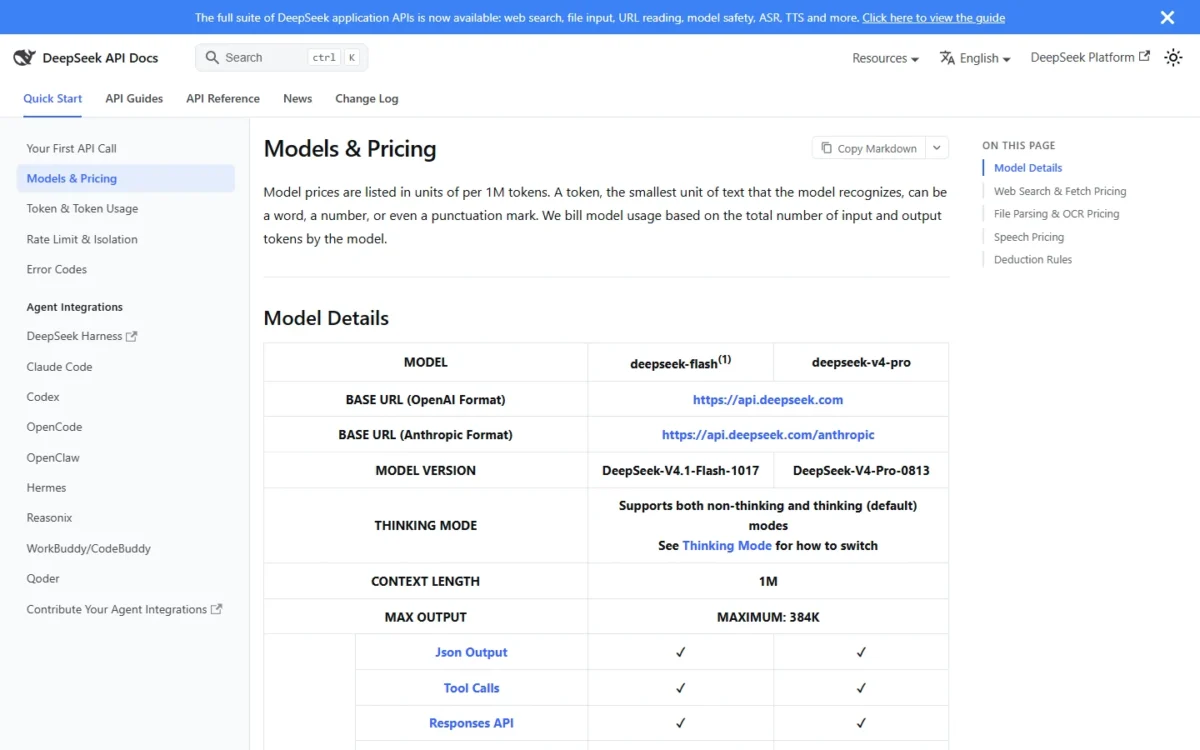
- Off-peak: $0.15 input and $0.60 output per 1M tokens; cache hit $0.003
- Peak: $0.30 input and $1.20 output per 1M tokens
Sources: DeepSeek models and pricing, checked November 2026.
Pros
- Half price off-peak, which covers the whole US workday
- 384K maximum output, three times the cap on Claude and GPT-6
- Open weights, vision support, and OpenAI- and Anthropic-format endpoints
Cons
- Rates double in the two weekday peak windows
- 31st on BenchLM
- GPT-6 Luna and Claude Haiku 5.5 list lower token prices
- Skip it if:
- your traffic is interactive and falls in the 8 to 11 p.m. Eastern window, when the peak rate applies. GPT-6 Luna charges one flat rate.
5. Kimi K3.1 Pro: Best Open-Weight Model by Third-Party Rankings
Open weights usually mean giving up rank, and Moonshot AI’s Kimi K3.1 Pro gives up the least. LLM Stats, checked November 15, 2026, names it the best open-weights model, and Artificial Analysis has it as the highest-ranked open-weights model with an Intelligence Index of 46, ahead of DeepSeek V4.1 Flash at 33. You pay a closed-flagship rate for it, the same as GPT-6.1 Sol.
BenchLM reads the family differently: it lists K3.1 Pro 18th at 70.4, one row below the older Kimi K3, which it still names its best open-weight model. The K3.1 Pro score carries BenchLM’s Estimated label, so I read the gap as thin evidence on a new release.
Moonshot closed the K2 series to new users on October 31, 2026 and plans to retire it by the end of December 2026; my review of the Kimi K2.5 retirement explains what to move to.
Pick Kimi K3.1 Pro if open weights are a requirement and quality still has to sit near the closed flagships.
The API is pay as you go, with no subscription plan, and batch jobs bill at 60% of the standard price.
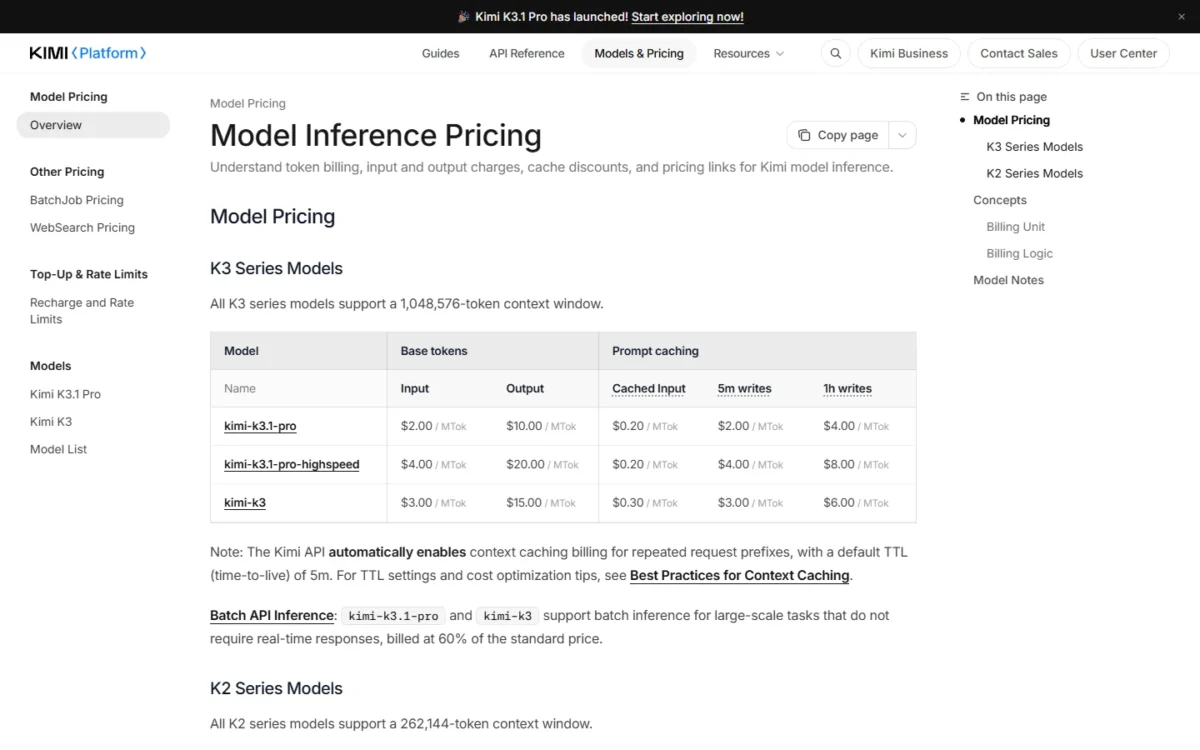
- kimi-k3.1-pro: $2.00 input and $10.00 output per 1M tokens
- Cached input: $0.20 per 1M tokens
Sources: Kimi model inference pricing, checked November 2026.
Pros
- Best open-weights model on LLM Stats and Artificial Analysis
- 1,048,576-token context, four times the K2 series’ 262,144
- Its predecessor, Kimi K3, is listed by Kimi as open source at 2.8 trillion parameters
Cons
- Token price matches closed models such as GPT-6.1 Sol
- BenchLM’s score for it is Estimated, one row below Kimi K3
- Kimi lists it as a 3T-class model, so size your hardware first
- Skip it if:
- you call the model for bulk work where rank matters less than price. DeepSeek V4.1 Flash keeps open weights at a fraction of the rate.
6. Grok 4.7: Best for Real-Time X and Web Search
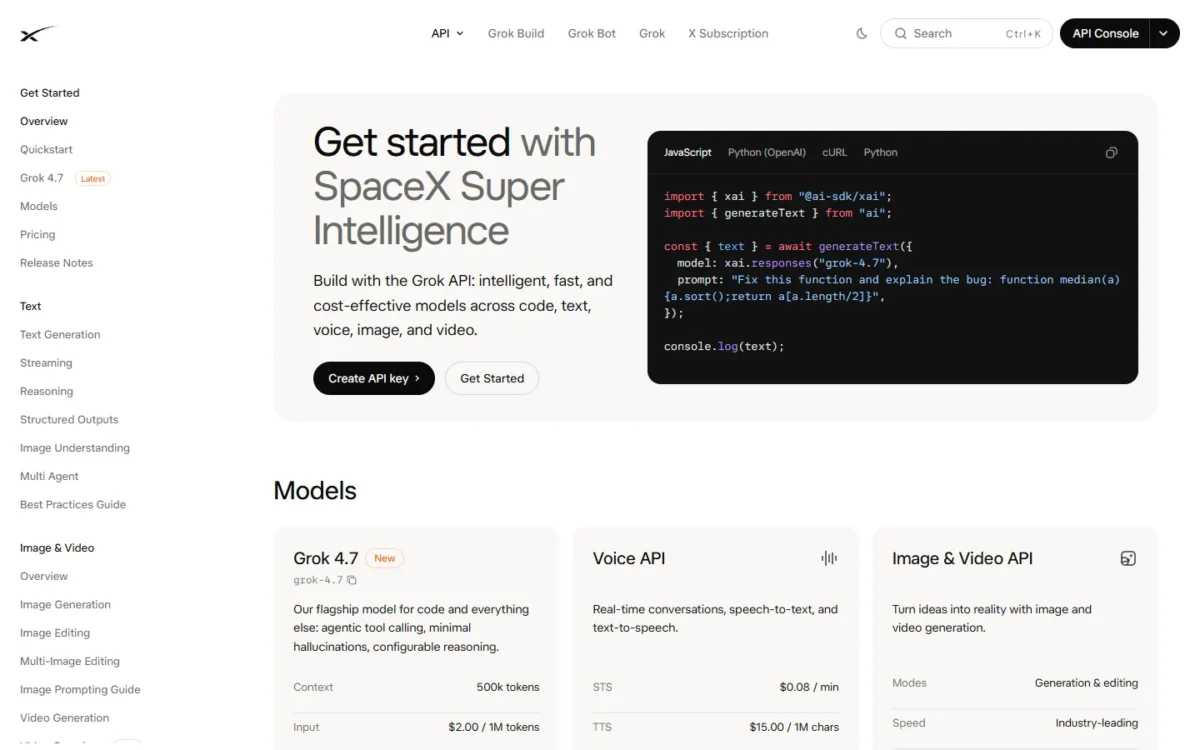
Grok 4.7 earns its place for one job: answers that depend on what was posted today. The docs of its maker, which docs.x.ai names SpaceXSI, pair the model with server-side Web Search and X Search tools, and state that without them Grok has no knowledge of current events beyond its training data. The window is the cost: 500,000 tokens, half the 1M of Claude, Gemini 4 and DeepSeek.
On price it undercuts its peers on output. Grok 4.7 matches GPT-6.1 Sol and Kimi K3.1 Pro on input but charges $6 per million output tokens where they charge $10, which helps apps that write long answers from search results.
I would choose Grok 4.7 when live X data is the product: brand monitoring, trend summaries, support triage on public posts.
Requests above 200K of context are charged different rates, and the model page links tool pricing separately, so budget search calls on top of tokens.
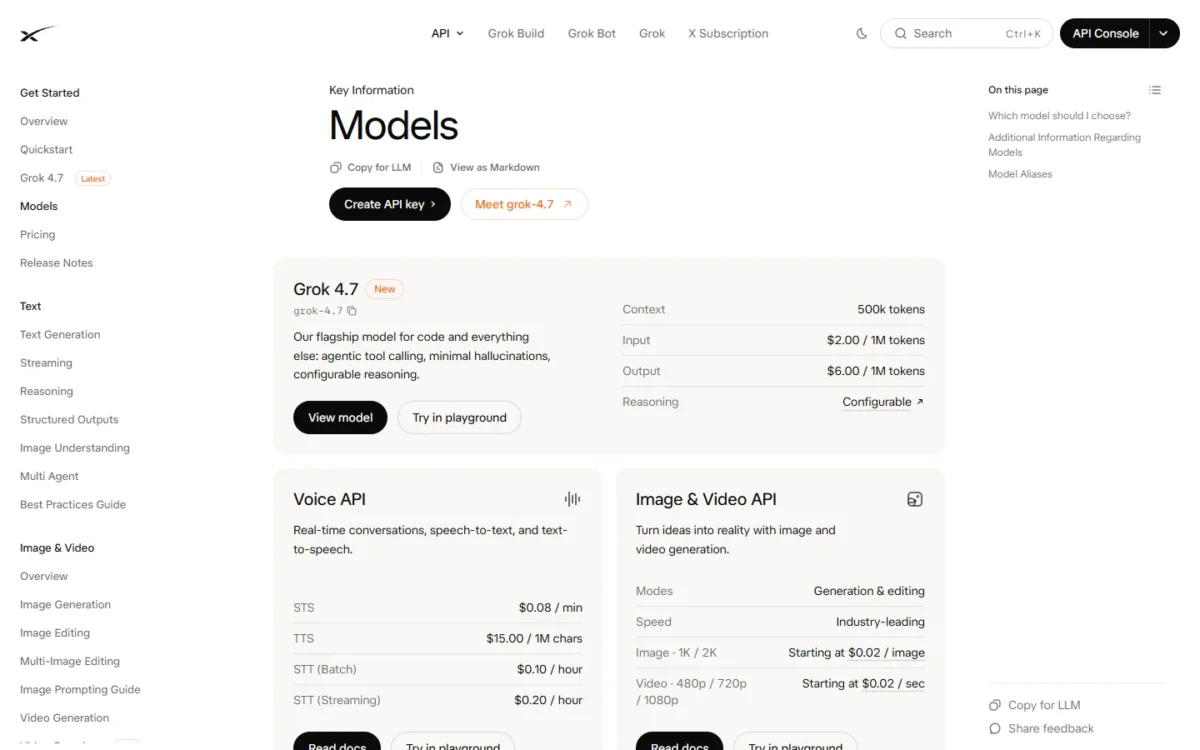
- grok-4.7: $2.00 input and $6.00 output per 1M tokens
- Cached tokens: $0.50 per 1M tokens
Sources: Grok 4.7, checked November 2026.
Pros
- Web Search and X Search tools for real-time data
- Lower output price than GPT-6.1 Sol and Kimi K3.1 Pro
- Function calling, structured outputs and Batch API support
Cons
- No knowledge of current events without the search tools
- 500,000-token context, half of the 1M on most picks
- Knowledge cutoff of May 2026
- Skip it if:
- you need more than 200K tokens of context at one predictable rate. Claude Opus 5.5 bills its full 1M window at standard pricing.
Grok is also sold as a subscription, and my ChatGPT vs Grok comparison covers that side.
7. Qwen3.8: Best for Running a Model on Your Own Hardware
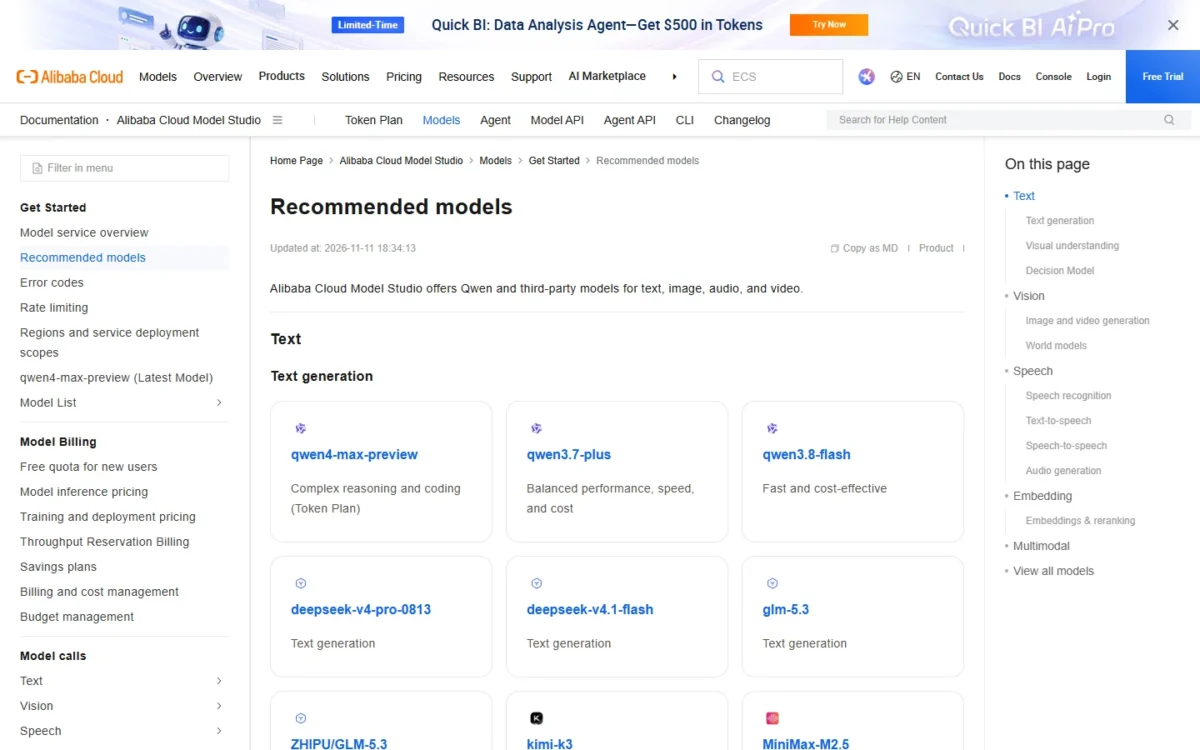
Qwen is the family to look at when the model has to run on hardware you control. Alibaba Cloud’s Model Studio files Qwen3.8 under “Qwen (open source)” as two models, qwen3.8-27b and qwen3.8-2.4t-a95b, so you can trial the small one before you size hardware for the large one. As a hosted model it is mid-table: Qwen3.8 Max held 35th place (63.6) on BenchLM as of November 13, 2026.
Hosted, Qwen3.8-Max costs the same as Grok 4.7, while Qwen3.8-Flash and Qwen3.8-Omni-Flash share a far lower rate.
Choose Qwen3.8 when self-hosting is the plan; hosted, it is worth it only for the Flash tiers.
Batch calls bill at 50% of the real-time price where a model supports them, and the free quota applies only in Singapore, for 90 days.
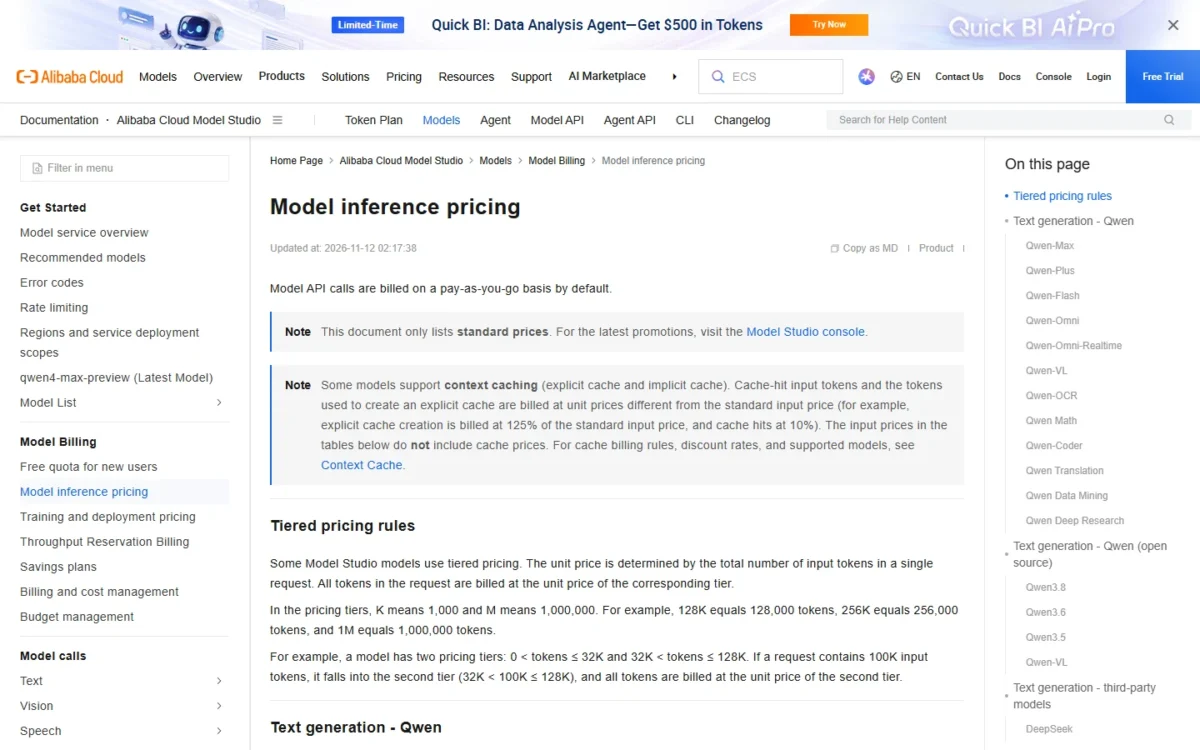
- qwen3.8-max: $2 input and $6 output per 1M tokens
- qwen3.8-flash and qwen3.8-omni-flash: $0.15 input and $0.47 output per 1M tokens
Sources: Model Studio pricing and Model Studio models, checked November 2026.
Pros
- Open-source Qwen3.8 in two models, qwen3.8-27b and qwen3.8-2.4t-a95b
- Flash tier with no peak-hour clock
- Omni-Flash handles audio and video analysis at the Flash price
Cons
- Qwen3.8 Max ranks 35th on BenchLM
- Free quota applies only in Singapore
- Batch and context-cache discounts cannot be combined
- Skip it if:
- you want one hosted model near the top of the boards. Kimi K3.1 Pro costs the same on input and sits 18th on BenchLM.
8. Mistral Large 4: Best for a European Vendor With Open Weights
On price, Mistral’s flagship sits below every US flagship in the cost table, though Mistral’s pricing example names “Mistral Large”, not “Mistral Large 4”, so confirm the rate for the current version. Mistral Large 4 is open-weight and multimodal, and Mistral’s About page describes the company as “a European leader”, which makes this the pick when the supplier has to be European. The trade-off is rank: 84th on BenchLM as of November 13, 2026, at 52.1.
Open weights are not a free commercial license either: Mistral’s FAQ says commercial deployments require a Mistral license.
Mistral deprecated Mistral Medium 3.5 and Mistral Large 3 on October 31, 2026, naming Large 4 as the alternative for both.
I would shortlist Mistral Large 4 when procurement asks for a European supplier, or when one API should reach Mistral, GLM and DeepSeek models.
On the API, batch processing takes 50% off and cached input up to 90% off. The consumer plans do not name the model they run.
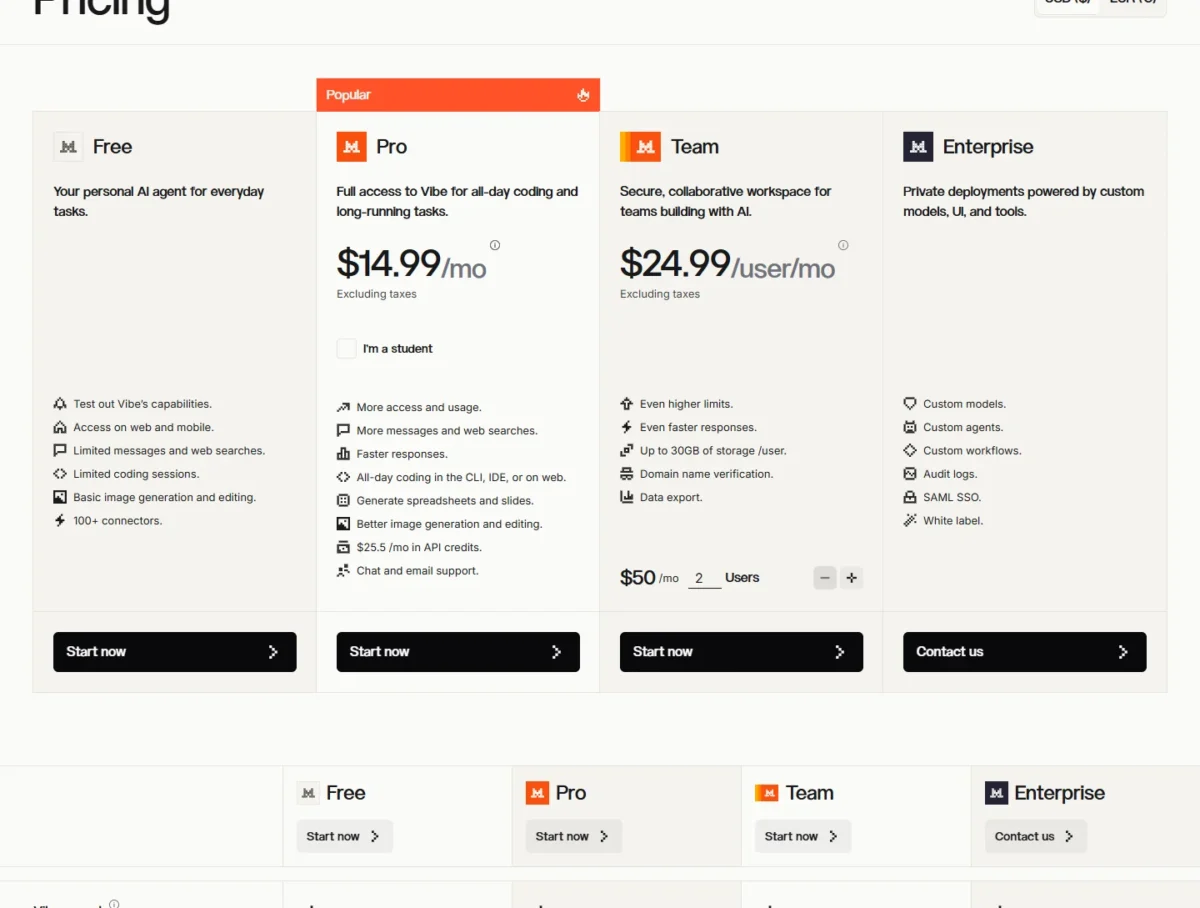
- Pro: $14.99 a month, excluding taxes
- Team: $24.99 per user a month, excluding taxes
Sources: Mistral pricing and Mistral models overview, checked November 2026.
Pros
- Lowest flagship token price in the cost table, as Mistral Large in the pricing example
- Open-weight and multimodal, from a European company
- The same platform hosts GLM 5.3 and DeepSeek V4.1 Flash 1017
Cons
- 84th on BenchLM
- Context window not listed on the models overview
- Commercial deployment of the open weights requires a Mistral license
- Skip it if:
- third-party rank decides your shortlist. Kimi K3.1 Pro sits 66 places higher on BenchLM.
9. GLM-5.3: Best for Budget Agentic Coding
GLM-5.3 makes more sense as a coding subscription than as a per-token API. Z.ai’s GLM Coding Plan runs on a points quota, charges half the points for calls made off-peak, including all day on weekends, and works with more than 20 agent tools, Claude Code among them. The model itself reads text only, with a 1M-token context, and holds 48th place on BenchLM (61, as of November 13, 2026).
Both upper tiers cut the price per unit of usage: Pro costs 4.4 times Lite ($80 / $18) for 6 times the usage, Max 9.3 times ($168 / $18) for 14 times. Lite costs $12.6 a month on yearly billing to Claude Pro’s $17 billed annually, and GLM-5.3’s API lists $1.4 / $4.4 per million tokens to Opus 5.5’s $4 / $20. The plan’s credit rules get a full section in my GLM-5.3 review.
For a solo developer who runs a coding agent every day, I would start on Coding Plan Lite. If your agent must read screenshots, use GLM-5.3-Flash on the API, which Mistral’s docs describe as multimodal.
Prices below come from the plan page’s Monthly view; its Yearly view takes 30% off.
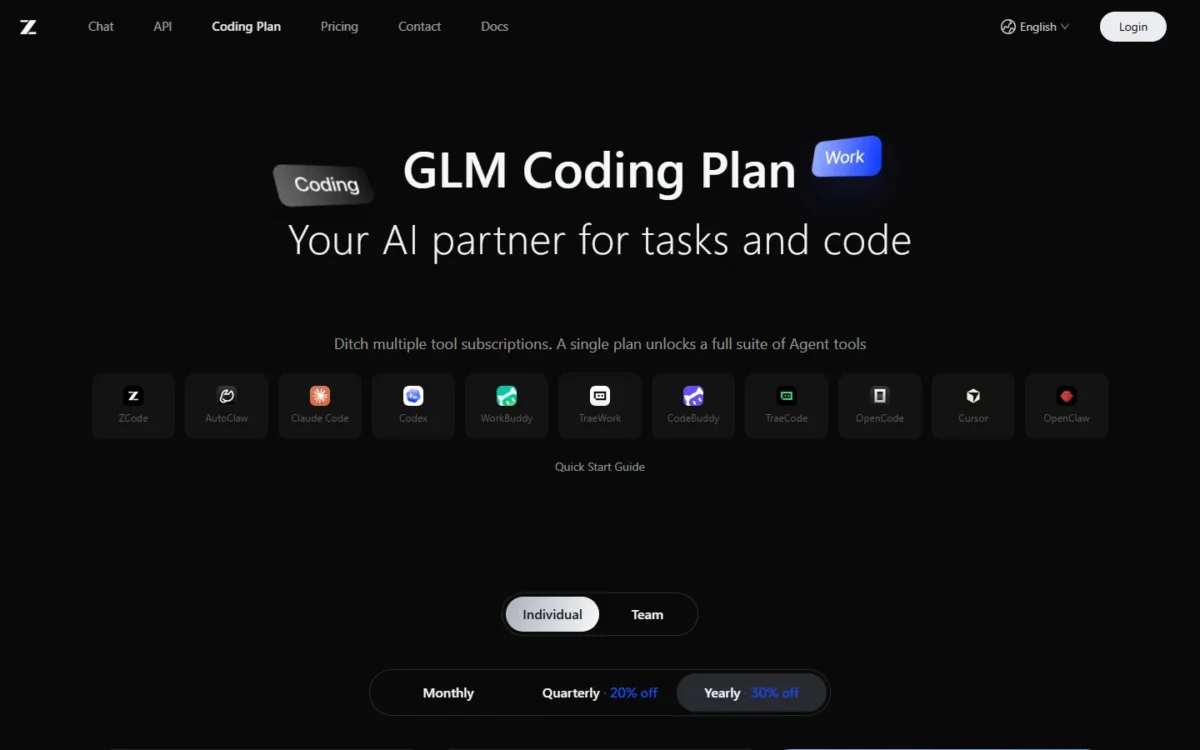
- Lite: $18 a month, 10,000 credits a week
- Pro: $80 a month, 6 times Lite’s usage
- Max: $168 a month, 14 times Lite’s usage
Sources: GLM Coding Plan, checked November 2026.
Pros
- A coding subscription with off-peak calls at half the points
- 1M-token context and 128K maximum output
- Third among open-weights models on Artificial Analysis
Cons
- Text-only input on GLM-5.3
- Reasoning is always on
- 48th on BenchLM
- Skip it if:
- your agent has to read screenshots or diagrams. Use Gemini 4 Carbon, or DeepSeek V4.1 Flash, which lists vision support.
10. Muse Spark Open: Best US-Made Open-Weight Model
Muse Spark Open homepage, llama.com, captured Nov 2026
Muse Spark Open is on this list for where it comes from, not where it ranks. Meta’s developer site, which now opens with Muse and keeps Llama under its docs links, offers it as an 816B open-weight model for agentic coding and calls it “the most capable US open-weight model to date”. BenchLM’s table, as of November 13, 2026, has it 103rd at 50.7, a score it marks Estimated.
Muse Spark Open is worth it when US origin is a hard requirement and you can serve an 816B model yourself; otherwise Kimi K3.1 Pro sits 85 places higher on BenchLM.
Meta’s developer page lists no per-token price, so budget your own serving cost on the open weights, or the rate of a hosted route.
- Hosted: Meta Model API, OpenRouter or Google Cloud
- Self-hosted: SGLang, vLLM or Apple MLX
Sources: Meta’s developer page, checked November 2026.
Pros
- Open weights from a US maker, at 816B
- Three serving stacks named, plus fine-tuning
- Hosted routes through Meta Model API, OpenRouter and Google Cloud
Cons
- 103rd on BenchLM, with an Estimated score
- No per-token price on Meta’s developer page
- Meta’s stronger Muse Wonder models are proprietary
- Skip it if:
- you need a listed per-token price to budget. Every other pick in this list prints one.
How to Choose the Best AI Model
Four questions settle the choice, in this order:
- What is the job? Pick Claude if you build coding agents, Gemini 4 if the input is mixed media and Grok 4.7 if you need live data.
- API or plan? Per token, compare the cost table. Per month, check which plan lists the model: Claude Pro for Opus, ChatGPT Plus for GPT-6 Astra, Google AI Ultra for Gemini 4 Carbon.
- How much volume? At millions of tokens a day, start with GPT-6 Luna or Claude Haiku 5.5 ($0.10 / $0.50) or DeepSeek V4.1 Flash off-peak ($0.15 / $0.60), then use Anthropic’s 50% Batch API discount, Kimi’s batch rate at 60% of standard or DeepSeek’s off-peak window.
- Must the weights be open? Six picks qualify: DeepSeek V4.1 Flash, Kimi K3.1 Pro, Qwen3.8, Mistral Large 4, GLM-5.3 and Muse Spark Open.
If you want the coding tool rather than the model, my list of AI coding tools by job starts where this one stops.
For literature reviews and cited answers, the AI tools for research list is the better starting point.
Best LLM vs best AI model: is it the same question?
For text work, yes: every pick here is a large language model (LLM), so the best LLM for your job is the same pick. “AI model” is the wider term. The same makers also sell image, speech and video models, such as Google’s Nano Banana Pro, which my list of image generators by job ranks.
Model or chatbot app?
Pick the app if you will only chat, and the model if you build on an API or pay per token.
Also Considered
Also on the long list:
- Claude Mythos 5.2: priced the same as Fable 5.2, which Anthropic names for demanding reasoning.
- Muse Wonder Full: proprietary, 15th on BenchLM (Estimated), with no listed token price.
- Llama 4 Scout: among the largest context windows on Artificial Analysis; Meta’s developer page now opens with Muse.
- Cohere Command A+: among the lowest costs per task on Artificial Analysis; Cohere prints token rates only for earlier Command models.
- MiniMax M3.1 Flash: fastest output on LLM Stats at 320 tok/s; speed is not a criterion here.
- Phi-4 Multimodal: a latency leader on Artificial Analysis, not a job fit.
- ERNIE 5.5 Flash Preview: 13th on LLM Stats, still a preview.
- Gemini 3.1 Pro: listed by Google only as a preview endpoint.
FAQ
Which is the best AI model currently?
By job: Claude Opus 5.5 for coding, GPT-6.1 Terra for writing, Gemini 4 Carbon for mixed media. By rank, Claude Fable 5.2 leads BenchLM, LMArena’s agent board and Artificial Analysis as of November 15, 2026; pick it only if Opus 5.5 falls short.
What are the top 5 AI models?
BenchLM’s top five are Claude Fable 5.2, Gemini 4 Carbon, Claude Opus 5.5, GPT-6 Astra (85.7) and GPT-6.1 Sol (84.6).
Which AI is better than ChatGPT?
Pick Claude if you build agents: LMArena’s agent board ranks Fable 5.2 and Opus 5.5 above GPT-6 Astra, which is seventh. Pick Gemini 4 Carbon if you need audio, video or PDF input, which OpenAI’s models page does not list for GPT-6.
What is the best free AI model?
For developers, pick Gemini 4 Hydrogen: Google’s free API tier charges nothing for its tokens, and BenchLM lists it 11th. Z.ai lists GLM-4.7-Flash as free on its API. For chat, ChatGPT Free runs GPT-6 Luna, and Claude Free includes Sonnet and Haiku.
Final Verdict: My Pick for Each Situation
My pick for each situation:
- Coding agents: Claude Opus 5.5.
- Writing and computer use: GPT-6.1 Terra.
- Audio, video and long PDFs: Gemini 4 Carbon, budgeted at its December 1, 2026 price.
- Scheduled bulk jobs on open weights: DeepSeek V4.1 Flash, off-peak.
- Open weights near the top of the boards: Kimi K3.1 Pro, at a closed-flagship price.
- Live X and web data: Grok 4.7, inside a 500,000-token window.
- Self-hosting at a size you choose: Qwen3.8, which Alibaba Cloud lists as open source in qwen3.8-27b and qwen3.8-2.4t-a95b.
- A European supplier: Mistral Large 4, worth it when vendor origin outweighs its 84th place on BenchLM.
- A coding subscription on a budget: GLM-5.3 through the GLM Coding Plan; text only.
- US-made open weights: Muse Spark Open, if you can serve it yourself.
Whichever row is yours, replay some of your own prompts on your top picks before you commit.